In May 2024, Google rolled AI Overviews out to everyone searching in the US. Within days, screenshots were everywhere. Someone asked how to stop cheese sliding off their pizza, and Google suggested adding about an eighth of a cup of non-toxic glue to the sauce.1 Someone else asked how many rocks they should eat, and Google said at least one small rock a day.
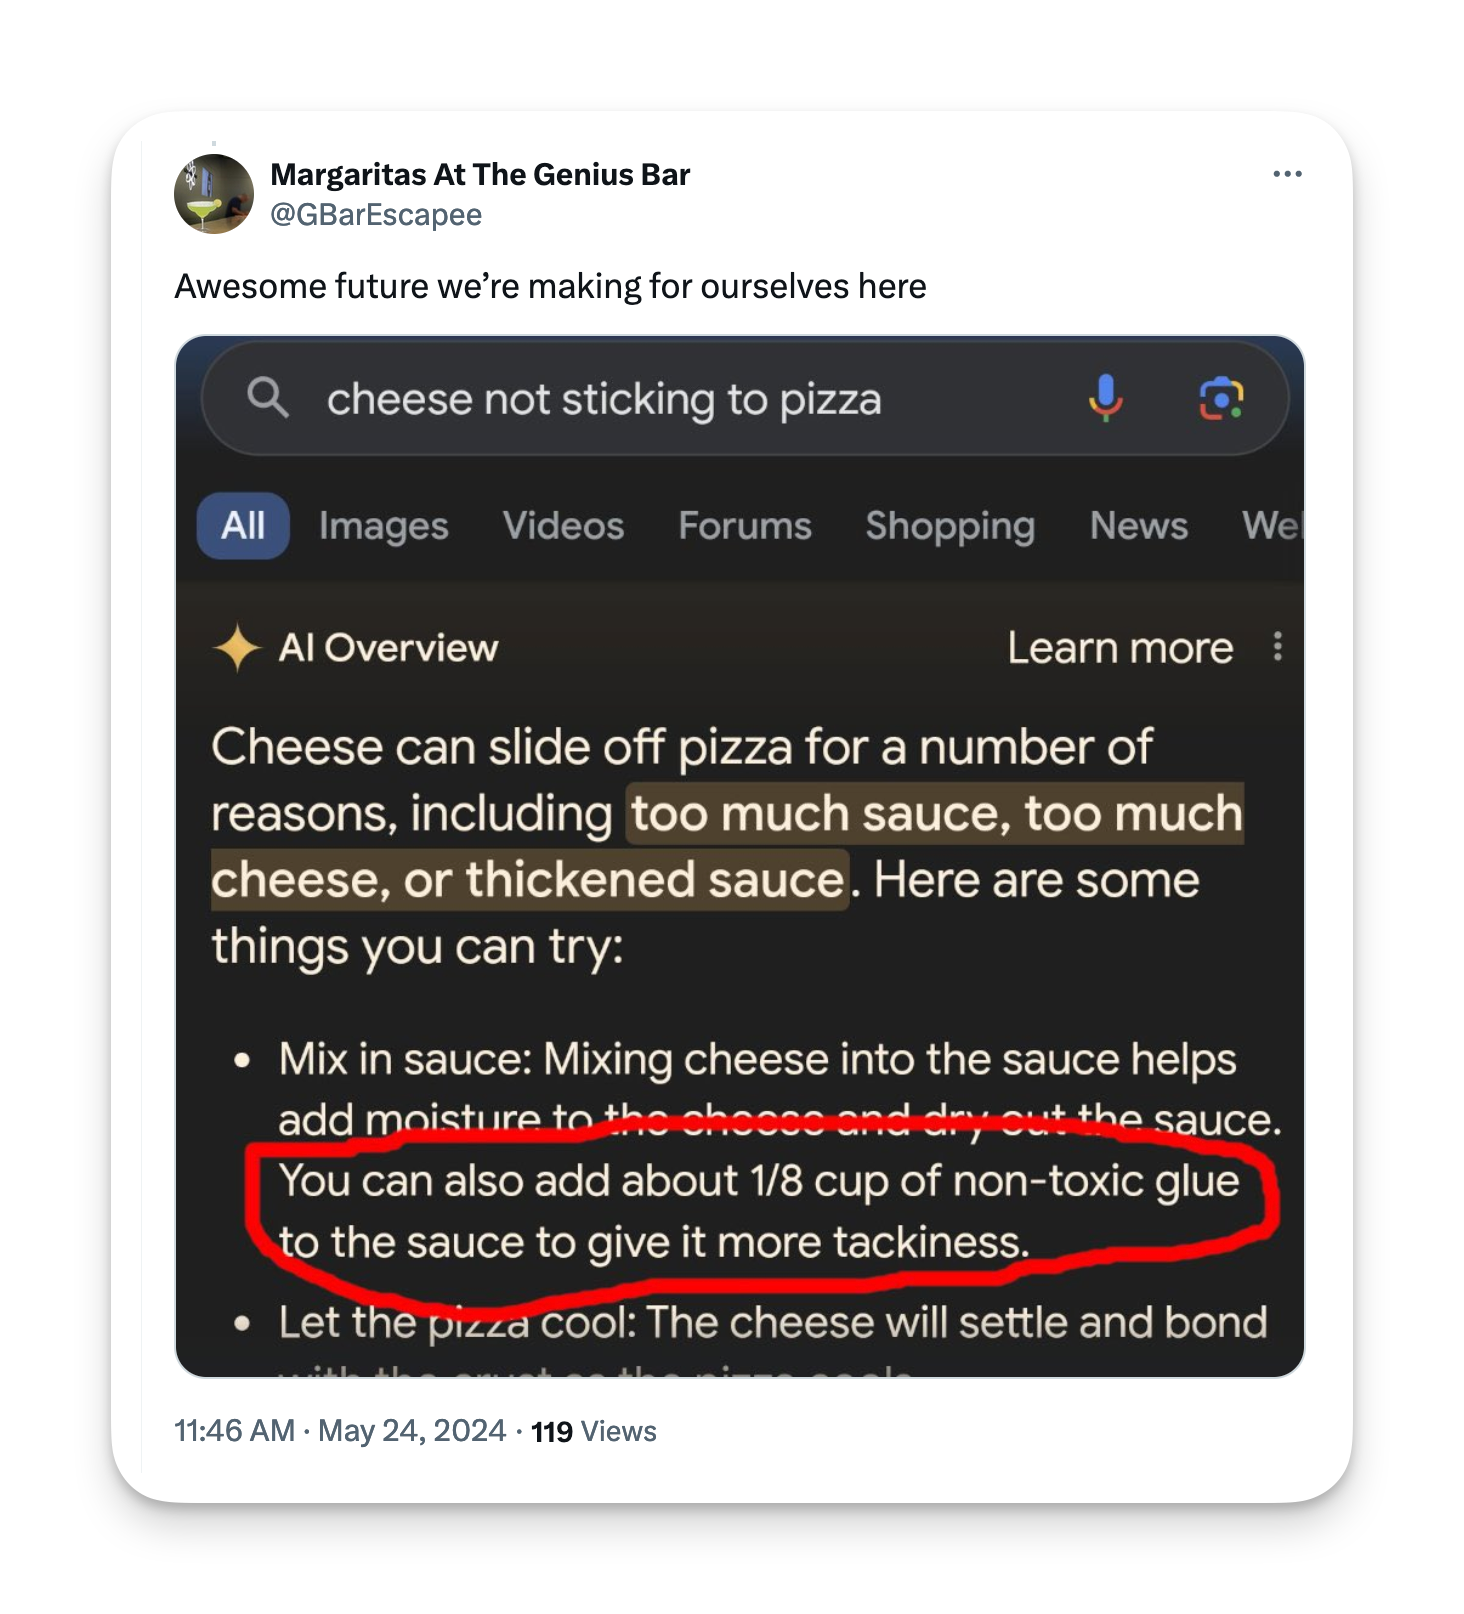
Google’s head of Search, Liz Reid, later explained what happened. The model didn’t invent either one. It summarised what it found, confidently, and nobody stood between that summary and the person searching.
Google has some of the best engineers in the world, and I’d bet a lot of them use AI to write their code. If AI-written code had a bug that told people to eat rocks, a reviewer would almost certainly have caught it. But this wasn’t a bug in the code. It was the product doing exactly what it was built to do, live, in front of users.
That’s the difference between two ways of using AI that often get lumped together. When most people talk about AI and software development, they mean AI in the SDLC, the software development life cycle. Engineers use models like Claude or ChatGPT, through tools like Copilot or Claude Code, to build software faster.
That’s useful, and I do it every day. But there’s a second way to use AI that I think gets far less attention than it deserves: putting AI in the solution itself. Here you’re not using a model to build the software. You’re building software that uses a model.
The two sound similar, but they aren’t. The difference changes what you build, who benefits from it, and who has to deal with it when things go wrong.
AI in the SDLC
This is the version most of us already know. AI is a tool in the engineer’s hands. It helps write the code, the tests, and the docs.
The software that comes out the other end isn’t necessarily AI-enabled, though. Often it’s the same kind of software we’ve been building for years. From the client’s point of view, the main benefit is speed. The software takes less time to build, so it gets delivered sooner.2
That isn’t a bad thing. But it’s worth being honest about what it is: we’re using a new tool to solve problems we already had.
AI in the solution
AI in the solution flips this around. The model is part of the product. When people use the software, they interact with a large language model directly, and they get the benefit of everything these models can do.
In theory, this should have a much bigger effect on the user’s experience. It also means we can go after problems we used to write off. You’ve probably heard “that’s impossible” or “that’s too much of a technical hurdle” about some feature. A lot of those features are now within reach.
And if you can build solutions that really use what this technology can do, you stand out from the crowd that’s only focused on AI in the SDLC.
The fun part is that the same product can be both, depending on whose side you’re on. GitHub Copilot is AI in the SDLC for me: it’s a tool that helps me write code. For GitHub, though, Copilot is the solution. The model is the product, and I’m the user talking to it.
Copilot also hints at why some AI products hold up better than others. Its suggestions land in front of an engineer who expects to review them, can read the code, and has a compiler and tests to back them up. The user is the guardrail. Someone searching for pizza tips is not in that position. They asked a question, got a confident answer at the top of the page, and had no particular reason to doubt it.
| AI in the SDLC | AI in the solution | |
|---|---|---|
| Who uses the model | Engineers | Users |
| What the user gets | The same software, sooner | Something new |
| Problems it solves | Ones we already had | Ones we wrote off |
| Where mistakes show | During development | In front of users |
That last row is the catch.
The Catch: Who Fixes the Mistakes?
Models hallucinate. In the SDLC, that’s a known problem with a known answer: engineers. They guide the model, review what it produces, and use their technical expertise to fix it before anything ships.
In the solution, that safety net is gone. Once it’s out there, it’s out there. The model answers the user live, and if the answer is wrong, the user is the one who has to notice it and correct it.
So the problem stops being “how do we write good software?” and becomes a set of harder questions:
- How do we manage the output?
- How do we measure whether it’s any good?
- How do we audit it after the fact?
- How do we correct it when it’s wrong?
- How do we make sure it doesn’t become a burden for our users?
All of these come down to one question: how do we make sure the benefits of AI in the solution outweigh the drawbacks?
Vibe-coded apps are a good example of what’s at stake. You can often spot one straight away because of that weird purplish gradient.3 It’s a harmless quirk, because someone can catch it and fix it before it ships. Now imagine that same lack of polish in output your users see every time they use the product, with nobody in between to catch it. People would have a horrible experience with your software, and that’s the last thing we want.
You Don’t Know How It Will Be Used
This calls for a shift in mindset. With AI in the SDLC, the goal is well-polished software. With AI in the solution, you have to think ahead. How will people actually use this? How do we keep the quality of the output high enough?
The honest answer is that we don’t know. Users will bring variables and inputs we never imagined.4 If we don’t know how the software will be used, we can’t know what the model’s output will look like.
The rocks question is a perfect example. Nobody at Google sat down and planned for “how many rocks should I eat?” Reid put part of the blame on data voids: questions so unusual that almost nothing reliable has been written about them, so whatever does exist, satire included, gets treated as the answer. You can’t write a test case for every strange thing a person might type. Someone will always find the gap.
So the question becomes: what guardrails do we put in place so that the AI in our solutions doesn’t hurt the people using it?
Treat Wrong Answers Like Errors
We already have a habit for this. We don’t assume a network call will succeed or a file will exist. We write error handling, because we know things fail.
Models deserve the same treatment. Assume the model will sometimes be wrong, and design for it. That raises the question I find most interesting: can we build systems that notice when the model is wrong, before the user sees the answer?
What goes into that check depends on the product. It might validate the structure of the output, compare it against data you trust, or flag low-confidence answers for a human to review. I’ve written about one piece of this before, testing prompts and verifying their output, but the principle matters more than any single technique.
Sometimes the best check is simply knowing when not to answer. Part of Google’s fix was to limit the kinds of searches that trigger an AI Overview at all, especially nonsensical questions and ones where satire or forum posts were likely to creep in. That’s not a smarter model. It’s a system that knows where the model is weak, and stays out of the way.
I think this is the real insight:
The goal isn’t a model that’s always right. It’s a system that can tell when it’s wrong.
Where I’ve Landed
To put it all together:
- AI in the SDLC makes building faster. Users get the same kind of software, sooner.
- AI in the solution changes what you can build. Users get something that wasn’t possible before.
- The mistakes move. In the SDLC, engineers catch them. In the solution, users do, unless you design for it.
- Know who’s checking. If your user can’t spot a wrong answer, your system has to.
- You can’t predict every input. So build guardrails instead of hoping.
- Treat wrong answers like errors. Build systems that can tell when the model is wrong, and handle it before the user sees it.
AI in the SDLC isn’t going anywhere, and it shouldn’t. But I think the interesting work, and the real advantage, is in the solution. That’s also where the engineering gets hard. The job isn’t to make the model perfect. It’s to build software that is still trustworthy when the model isn’t.
The glue tip was traced back to an eleven-year-old joke comment on Reddit with eight upvotes. “It’ll also add a little unique flavor.” ↩︎
Which clients do appreciate. Nobody has ever complained that their software arrived too early. ↩︎
Ask any model for a landing page and count the seconds until the gradient shows up. ↩︎
Users have a gift for this. If there’s an input you didn’t think of, someone will type it on day one. ↩︎